
AI usage often starts with a few subscriptions, a limited pilot, or one team experimenting with an API. Then adoption spreads, agents begin making many calls for each task, and the first serious usage bill arrives.
For many organizations, that bill is a shock. The immediate response is understandable. They look for a less expensive model.
Which model gives us the lowest cost per token?
Lower-cost models can reduce spend, but token price alone rarely produces the best operating decision.
A short request sent to an expensive model may still be inexpensive. A seemingly cheap model can become costly when an agent repeatedly sends a large context window, calls tools, retries failed steps, and runs across hundreds of employees. A local model has no provider token bill, but the hardware can be a poor investment if it sits idle or fails to meet the quality requirement.
The more useful question focuses on successful completion.
Where should this workload run, and what is the lowest-cost route that completes it successfully?
That turns AI cost optimization from a model-shopping exercise into a workload-placement discipline.
The Token Price Is Not the Business Metric
Token prices are useful for calculating an invoice. They do not tell you whether the work created value.
Two models can produce very different economics even when one has a lower published price. The less expensive model may require more retries, more human correction, or a second model to check its work. The premium model may cost more per request but finish a difficult task correctly on the first attempt.
For that reason, the unit that matters is not simply cost per million tokens. It is cost per successful task.
That measure can include the following.
- model and provider charges
- local infrastructure and operating costs
- agent steps, tool calls, and retries
- employee review and correction time
- failures that require the work to be repeated
This does not require a perfect financial model. It requires one consistent acceptance test. If three model routes are asked to complete the same task, the organization should judge them against the same quality, latency, and policy requirements.
Start With the Workload, Not the Model
A model catalog is a list of capabilities. A workload tells you what the organization actually needs.
Before choosing where a request should run, define four things.
1. The capability floor
What does a good result look like?
A short rewrite, classification, or summary may work well on a smaller model. Contract analysis, complex coding, or multi-source research may justify a more capable model. The objective is not to select the weakest possible option. It is to stop paying for capability the task does not use.
2. The data boundary
What information will enter the request, and where is that information allowed to go?
Public research, internal operating data, customer records, source code, legal material, and unreleased product plans may require different routes. Provider terms, retention settings, contracts, and the organization’s own policy all matter.
The answer is not always “keep everything local.” It is to make the approved data path explicit before the request reaches a model.
3. The operating pattern
How frequently will the workload run, and how predictable is the demand?
An occasional complex task may be a natural fit for an online model. A high-volume, recurring workload can justify private capacity because sustained utilization gives a fixed investment more opportunities to replace variable spend.
Agents make this especially important. One user action may trigger many model calls, and long-running workflows can repeatedly process the same instructions, tool definitions, history, and results.
4. The service requirement
How quickly must the task finish, how many people will use it at once, and what happens when the preferred route is unavailable?
A model fitting into memory does not prove that it can support the required concurrency. A low-cost provider is not useful if it cannot meet the availability requirement. Placement has to account for throughput, latency, fallback behavior, and operational support, not only model quality.
Three Places to Run AI Work
Once the workload is defined, most enterprise AI requests can be evaluated across three broad destinations.
| Destination | Often fits | Primary tradeoff |
|---|---|---|
| On-device | Private drafts, summarization, classification, short transformations, individual productivity | Limited by the device, model size, and local availability |
| Shared private capacity | Recurring internal workflows, sensitive team use, larger open-weight models, steady organizational demand | Requires infrastructure ownership, utilization, and operations |
| Approved online models | Frontier reasoning, specialized capabilities, burst demand, large multimodal or tool-heavy work | Variable spend and an external data path that must be approved |
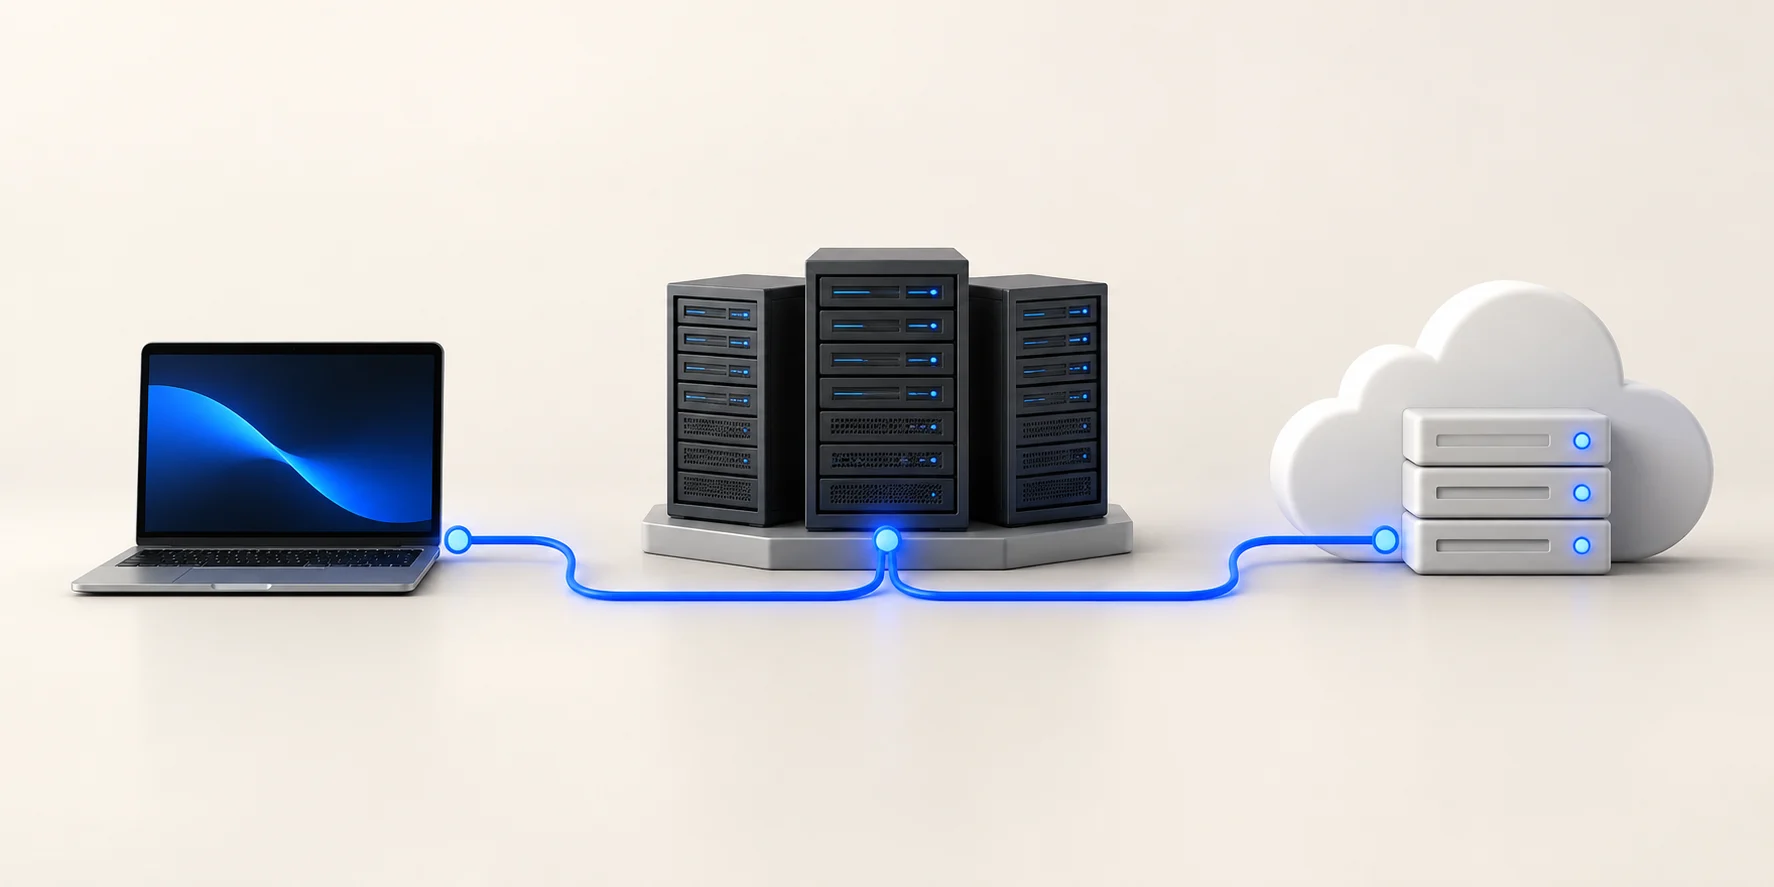
These are not competing ideologies, but rather different capacity options.
The strongest architecture is often hybrid. It uses local models for suitable routine or sensitive work, shared private infrastructure for heavier recurring demand, and approved online models where their capability or elasticity creates enough value.
Local AI Changes the Cost Curve, Not the Need for Measurement
Local inference replaces a variable provider charge with a combination of fixed investment and operating cost.
That can be attractive when the organization has sustained demand. The same request can run repeatedly without creating a new provider token charge each time. Hardware may also support software development, creative production, analysis, and other work when it is not serving AI requests.
But local does not automatically mean less expensive.
The investment can disappoint under the following conditions.
- usage is too low to keep the infrastructure productive
- the local model does not meet the quality threshold
- concurrency requires more capacity than expected
- operations, power, support, and deployment costs are omitted
- the comparison assumes that every cloud request can be displaced
The correct comparison counts only the work that can actually move. If 40 percent of a workflow still requires an approved frontier model, the business case should treat that online usage as a continuing cost.
This is why a break-even chart should be an output of workload testing, not the beginning of the decision.
Governance Turns Placement Into an Operating System
Workload placement becomes difficult when every employee and every application must make the decision independently.
People should not need to remember which provider is approved for customer data, which model is economical for a routine task, or which route has available private capacity. Applications should not need separate credentials and custom routing logic for every provider.
The policy belongs at the gateway.
Msty Nexus provides one control layer across local runtimes, shared private infrastructure, and approved online models. Organizations can use that layer to expose approved routes, protect provider credentials, apply guardrails, observe consumption, and choose a destination based on the work being performed.
Our AI Governance page shows how that model connects cost controls, sensitive-data handling, scoped access, and route visibility without forcing an organization into local-only or cloud-only AI.
The practical pattern follows four steps.
- An approved application connects to one gateway.
- The request is evaluated against the organization’s route and access policy.
- Nexus sends it to on-device, private, or approved online capacity.
- Usage remains visible by application, model, and team.
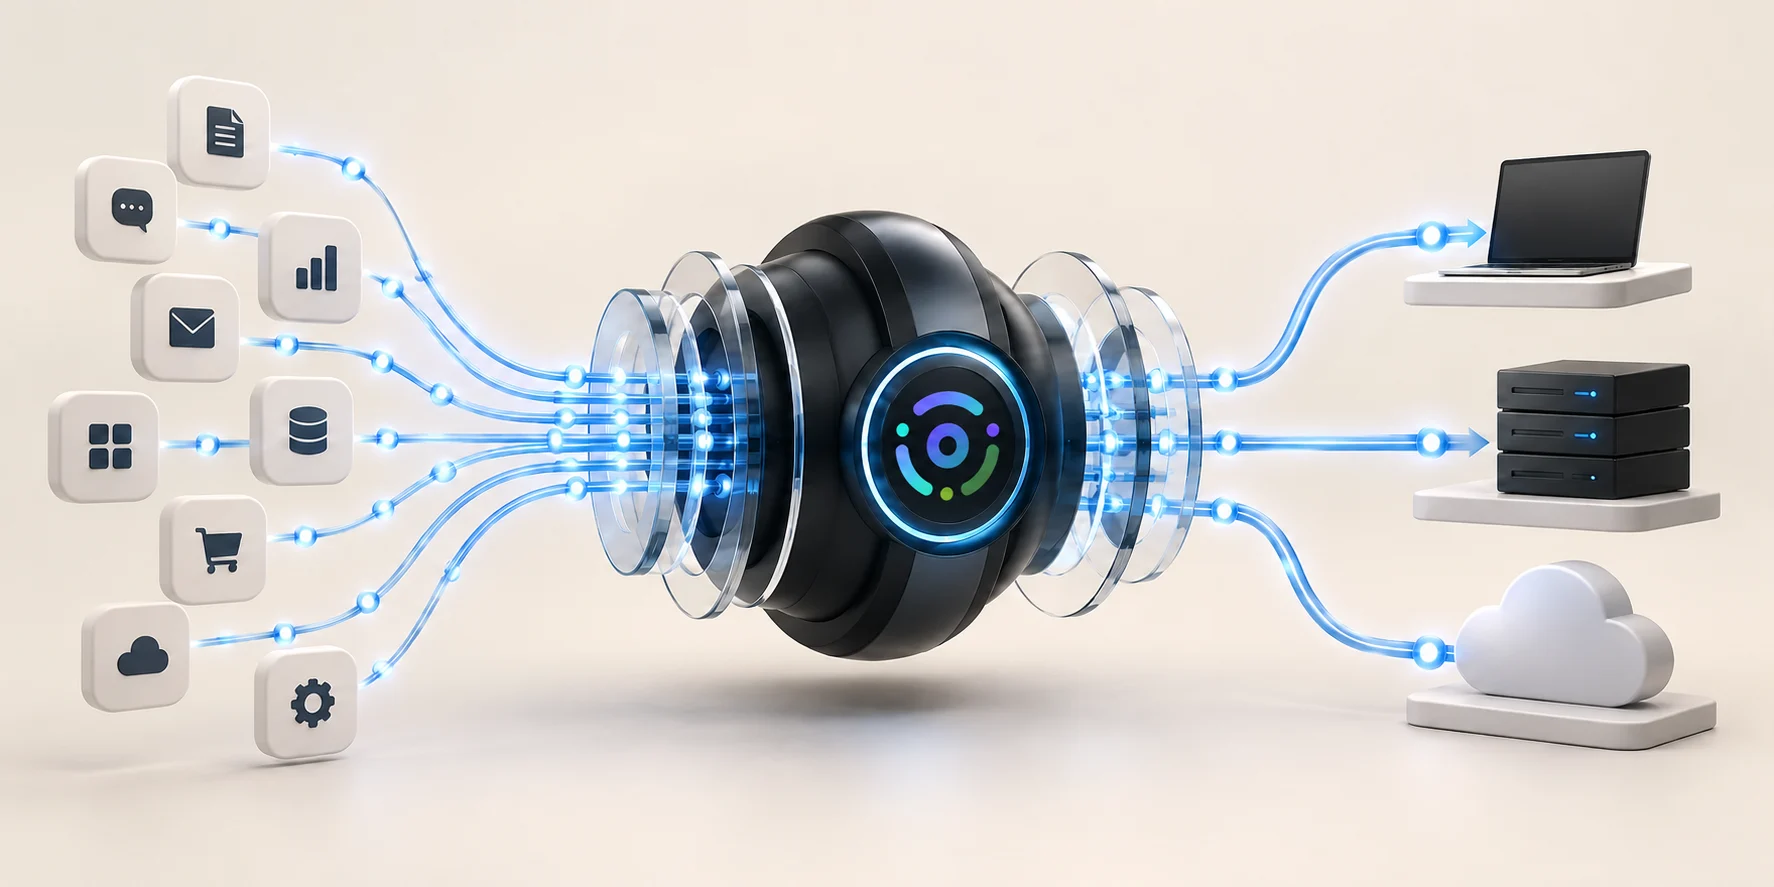
The exact outcome still depends on configuration. A gateway does not invent the organization’s policy or make every model equivalent. It gives that policy one place to be enforced and improved.
A Better First AI Cost Project
Organizations do not need to redesign their entire AI environment to begin.
Choose one workload with the following qualities.
- a clear owner
- enough recurring volume to measure
- a result that can be accepted or rejected
- known data-handling requirements
- a realistic alternative route
Then run the same representative tasks through a suitable local model, an efficient online model, and a premium model.
Measure the following.
- accepted results
- end-to-end completion time
- model, infrastructure, and review cost
- retries and fallback use
- policy exceptions
This produces a placement decision grounded in the organization’s own work. It may show that the local route is ready for production, that an efficient hosted model is the best default, or that the premium model earns its higher price.
All three are useful outcomes.
The Goal Is More Useful AI, Not Fewer Tokens
Cost control should not become a reason to suppress productive AI use.
The objective is to expand adoption without sending every request to the same model, through the same provider, under the same cost structure.
That requires a portfolio mindset and a control layer capable of putting it into practice.
- match capability to the task
- match the data path to policy
- match fixed capacity to sustained demand
- preserve approved online models for work that benefits from them
- measure cost at the level of a successful outcome
Msty Nexus provides that control layer. It gives organizations one gateway across local, shared private, and approved online models. Routing rules, access policy, provider credentials, and usage visibility can all be managed in one place. Teams can place each workload based on quality, data boundaries, and cost without building separate provider logic into every application.
The future of enterprise AI is unlikely to be one model or one location. It is a governed mix of models and infrastructure. Msty Nexus helps organizations manage that mix and place each workload where quality, control, and economics meet.
Explore AI governance with Msty Nexus or learn more about Msty Nexus.